Coding & agents𝕏
swyx
@swyxmore conferences could implement this. so much high value time wasted without thought https://t.co/jn93l7JyoH
Improve how you give agents context, break down tasks, test changes, and ship software.
Topic editions via RSS ↗swyx
@swyxmore conferences could implement this. so much high value time wasted without thought https://t.co/jn93l7JyoH
OpenAI Developers
@OpenAIDevsGPT-6 Astra helps @harvey turn stacks of documents into structured legal drafts, so lawyers can focus more on strategy. https://t.co/Cm283IUzet
LangChain
@LangChainIntroducing Trajectories in LangSmith. A view of agent behavior that everyone on the team can understand at a glance. https://t.co/8s9kHol2LO https://t.co/8cGrmhVa2F
LangChain
@LangChainAnd that’s a wrap on Interrupt NYC. See you in London! https://t.co/Bh7VNhyXkf
Visual Studio Code
@code🚀 From our VS Code Learn library: Extending Agents! In this E2E tutorial, we'll explore key aspects of AI Agents with Tools, Tool sets, Permissions and Sandboxing. We'll also look at MCP (Model Context Protocol) and how to use it to connect your agents to external data sources. Check it out ▶️ https://t.co/L4T3cpW8kF
LangChain
@LangChainThe talks may be over, but the Interrupt Reception sponsored by @tavilyai has just begun! https://t.co/8TheQp5ReJ
LangChain
@LangChainFinal sessions of Interrupt NYC 🎙️ Fireside Chat w/ @RogoAI CEO & Co-Founder @gabestengel 🎙️ Evaluating Agentic AI at Scale with @linkedin https://t.co/kLEMO6bftf
LangChain
@LangChainBefore Interrupt wraps up, stop by the LangChain Agent Arena! 🕹️ Play 30 seconds of Tetris to train your style 👉 Choose the model that plays it for you 👀 Watch it battle the reigning champion https://t.co/tSVU2zvcCz
LangChain
@LangChainA few things you can build: 1️⃣ Annotation queues: Review and label one (or many) runs at a time 2️⃣ Experiment comparisons: Compare outputs and metrics across experiments side by side 3️⃣ Trace reviews: Build trace or thread history views to inspect app behavior https://t.co/FlkGPcfsHV
LangChain
@LangChainAnother awesome feature in Managed Deep Agents 0.8
LangChain
@LangChainManaged Deep Agents 0.8 makes the Slack experience even better!
LangChain
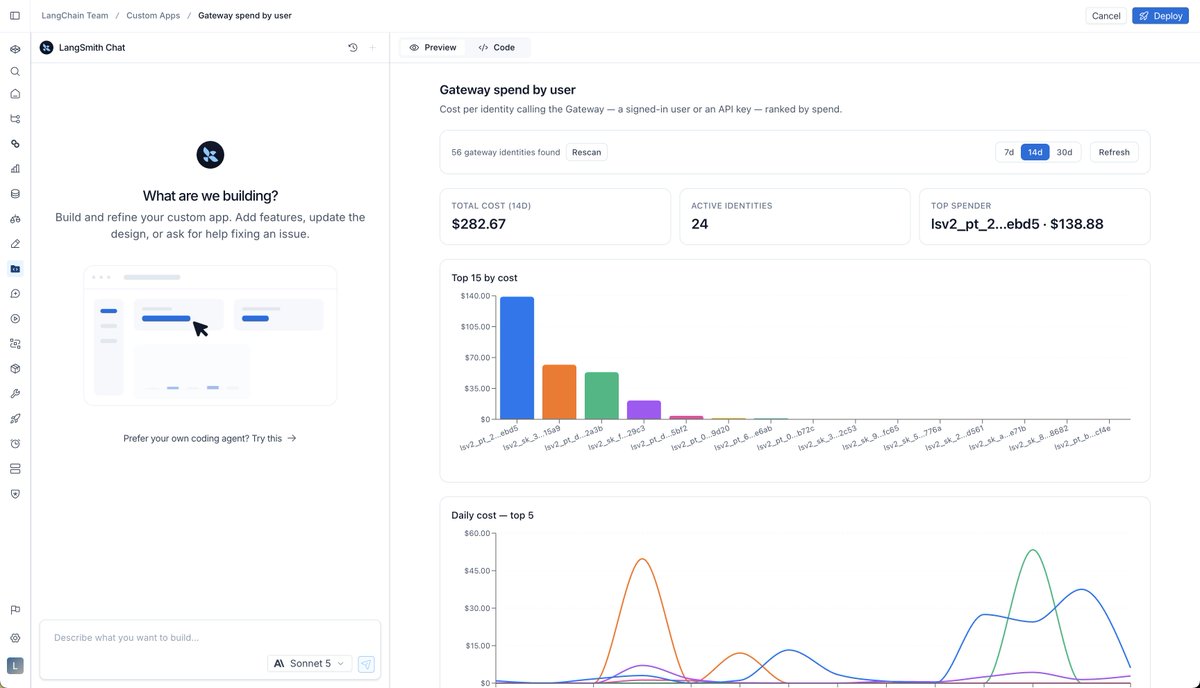
@LangChainIntroducing LangSmith Custom Apps Create any interface from your agent data with a prompt. If you can think it, LangSmith can build it. Now GA. https://t.co/MayBpUbPdu https://t.co/9AODngofKx
LlamaIndex 🦙
@llama_indexconfidence scores only matter if they help you decide what to automate. for document extraction, that usually means knowing how much work you can safely accept at a given precision target. in our latest post, we look at confidence scoring through that lens, including: ✅️ confidence cutoffs ✅️ precision vs. recall ✅️ score coverage ✅️ score granularity ✅️ human review volume using ExtractBench, we compare how different extraction systems perform after confidence filtering. at a 97% precision target, LlamaParse Agentic Plus reached 66.48% recall on expected fields after filtering. the useful part of a confidence score isn’t the number itself. it’s whether you can use it to control automation and review in production. 👉️ read the full post: https://t.co/U462MW2JOf
LangChain
@LangChainUp next at Interrupt 🎙️ Fireside Chat w/ @OpenRouter CEO & Co-Founder @alexatallah 🎙️ Building Engine: How we approach agent improvement w/ @bentannyhill https://t.co/0u7XviPsOJ
LangChain
@LangChainInterrupt NYC Swag spotlight: ⌨️ A clicky fidget keycap ❄️ LangChain Sweatshirt 🖊️ Pens https://t.co/iEZPrgo5gV
LangChain
@LangChainThe LangSmith Engine that could (be won) https://t.co/RENVfRAGO5
LangChain
@LangChainIntroducing LangSmith Fine-Tuning and the smithtune CLI. LangSmith now handles the entire fine-tuning process. Use your traces to train specialized models that cut cost and latency. Now in Public Beta. https://t.co/hhH5Tvlm7e
LangChain
@LangChain1️⃣ Identify + export trajectories from LangSmith 2️⃣ Transform traces into SFT-ready training examples 3️⃣ Fine-tune open models w/ @baseten + @fireworks_AI 4️⃣ Evaluate in LangSmith All in one simple workflow. https://t.co/mbDEs4eT6z
LangChain
@LangChainWhat is a trajectory? A conversational view of an agent session that pulls together: ✅ Human messages ✅ AI messages ✅ Tool messages ✅ System prompts …across the main agent + any subagents, then shows them in the order they first appeared.
LangChain
@LangChainAfter lunch, here’s what’s up next at Interrupt: 🎙️How @airbnb built Agentic AI on LangGraph 🎙️Deploying mission-critical agents to production w/ @VictorMoreira16 🎙️LangSmith for Mental Health AI w/ @SpringHealth https://t.co/ymkqOQrvYk