This week brought a wave of vendor announcements for coding agents, from new frontier models and cheaper inference to observability, rollouts, and parallel execution surfaces.
OpenAI Developers said GPT-6 Sol and Luna launched with API prices 50% lower than GPT-5.6, and that GPT-6 prompt caching was improved with higher default cache-hit rates and cached-input discounts of up to 90%.
Cognition said GPT-6 Sol and Luna are available in Devin, with Sol matching GPT-5.6 Sol on FrontierCode 1.1 at 61% lower cost per task and Luna scoring above GPT-5.6 Luna at roughly a quarter of the cost.
We serve data in milliseconds to more than 1.2 billion users across 40 geographic regions.
To reach that scale, we worked closely with @AzureCosmosDB on our storage architecture, achieving a 12x improvement in global median read latency. https://t.co/h5sRJaQABs
Today we're introducing a refreshed Devin Desktop app, with an agent command center designed to be smoother and more polished than ever before. https://t.co/4SAMxsKOwG
*taps sign*
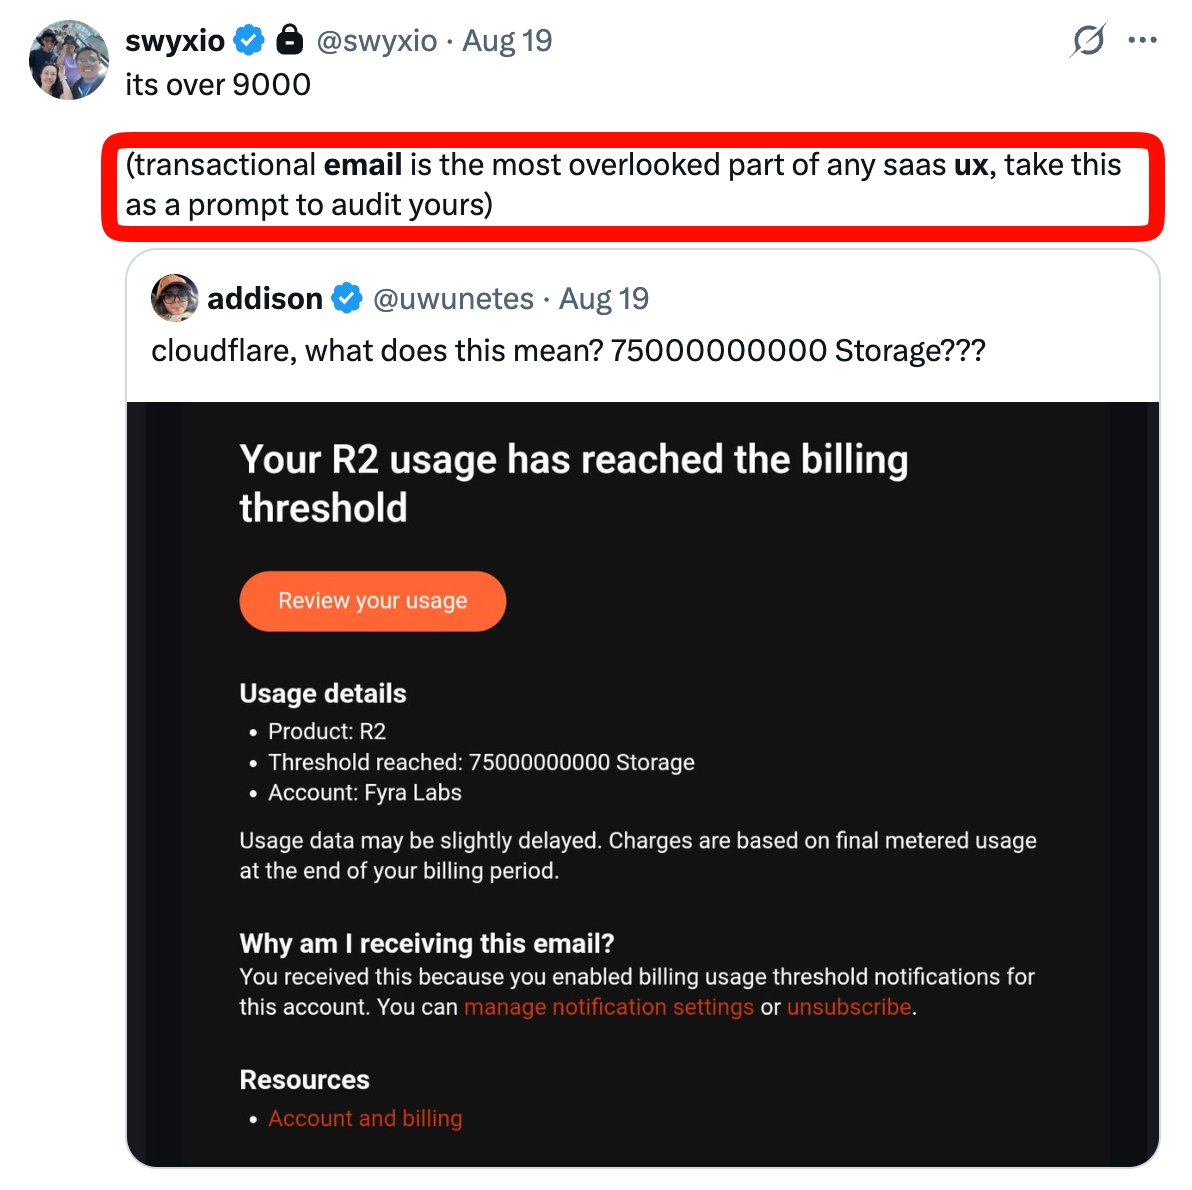
read your own emails your apps send out. particularly if they are being vibecoded. real humans still care and do read them. https://t.co/R5JFvYuUgp
i shit you not this was a legit trade that @goodalexander made in our $1B hedge fund days and it has printed for well over a decade at this point
markets are not efficient and the ribs are good
Computer Use lets agents click and type across any app on your computer, not just the browser.
Cursor uses it on its own when a task needs it. You can also ask for it by @-mentioning Computer Use in your prompt.
Update Cursor to try it: https://t.co/vwTPMUSnyd
Yesterday we launched OCRia-1, our new state-of-the-art document parsing model powering LlamaParse.
Today, it’s on OpenDocRouter! Run it alongside other parsing models on your own documents and see how it compares on accuracy, speed, and cost.
Set the model to llamaindex/ocria-1 in your parse request to try it. New accounts start with $5 in credit: https://t.co/Ub6FOKZaKa
Try OCRia-1 on LlamaParse today : https://t.co/rzaFHLeFH1
We reserved broad replication for small, critical datasets like authentication metadata needed on every request.
In-region caches served frequently accessed data, such as settings and application state.
Lastly, rewriting the service layer in Rust reduced proxy overhead. https://t.co/AG91TlI4KO
Together, caching, replication, and the Python-to-Rust rewrite brought global median read latency from ~120ms to ~10ms.
Product teams also have less infrastructure to manage, allowing them to move faster.
https://t.co/rSCASCnxtE
The best of Interrupt, now on demand.
Access our archive today and start watching our sessions from Interrupt San Francisco, NYC, and London. https://t.co/hL8WUWHbjG
Continual learning is about to get boring, in a good way.
@willcb from @primeintellect took the stage at our recent Learning Loop event to make the case.
If you're thinking about how continual learning fits into the way your team already ships software, this full 21-minute session is a good place to start.