See what’s being reused and what’s preventing cache hits.
Track cache-hit rates in the new Prompt Caching Dashboard on https://t.co/9eDbe9PbGF.
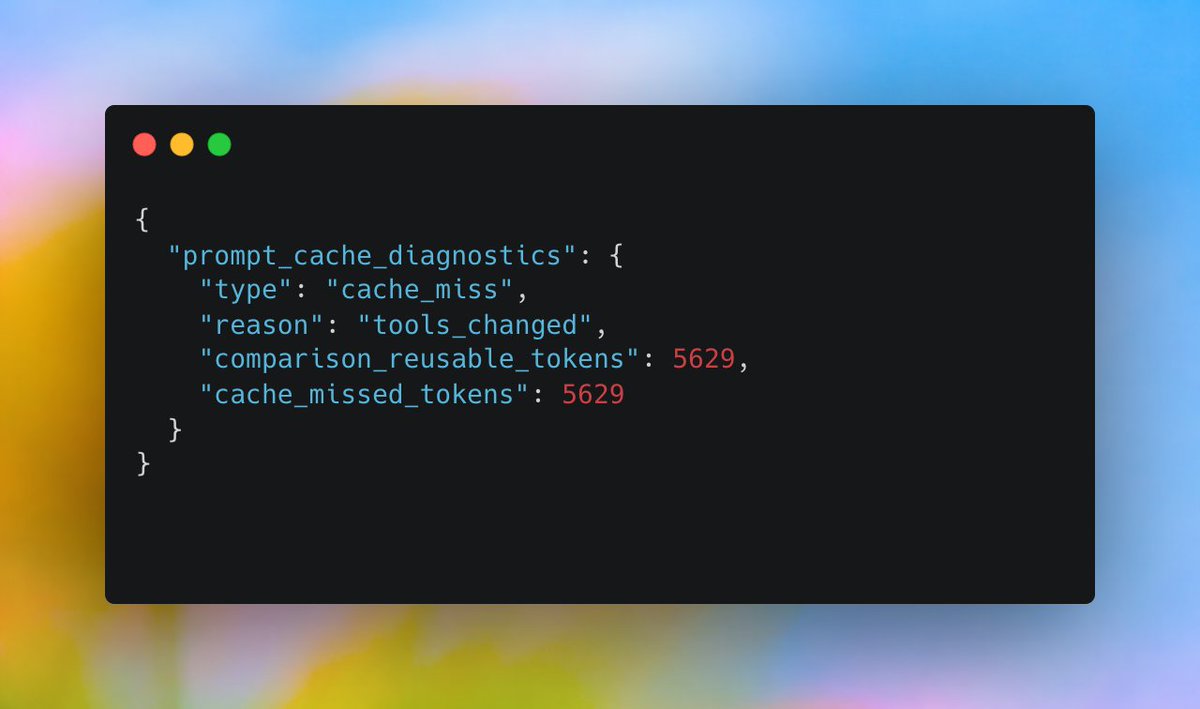
Use the diagnostics API to identify changes that prevented reuse and estimate how many tokens were affected. https://t.co/M16n4rG1Cl
🚀 Claude Opus 5.5 is now available in VS Code with GitHub Copilot.
Built for agentic coding, long-running tasks, and knowledge work. Give it a try today!
https://t.co/CkQzmZUVPS https://t.co/b66z7s00qs
🏃🏽♂️Agent Merge: Keep Your PR Moving in VS Code
Discover Agent Merge (Experimental) in VS Code, a powerful way to keep your pull requests moving after they’re open. Let the agent handle review comments, failed checks, and merge conflicts, apply the necessary fixes, rerun builds and tests, and keep working until your PR is ready to merge.
➡️ https://t.co/9nQZZJ6SlP
📣 @OpenAIDevs's GPT-6 family is expanding in GitHub Copilot with two additional models now generally available.
☀️ GPT-6 Sol: the balanced model for interactive and agentic coding.
🌕 GPT-6 Luna: a lightweight, cost-efficient model for smaller tasks and the lowest-cost option in the family.
Try them in the GitHub Copilot app or @code.
https://t.co/gyEGwnYxFT
GPT-6 Sol and Luna are now available in Devin.
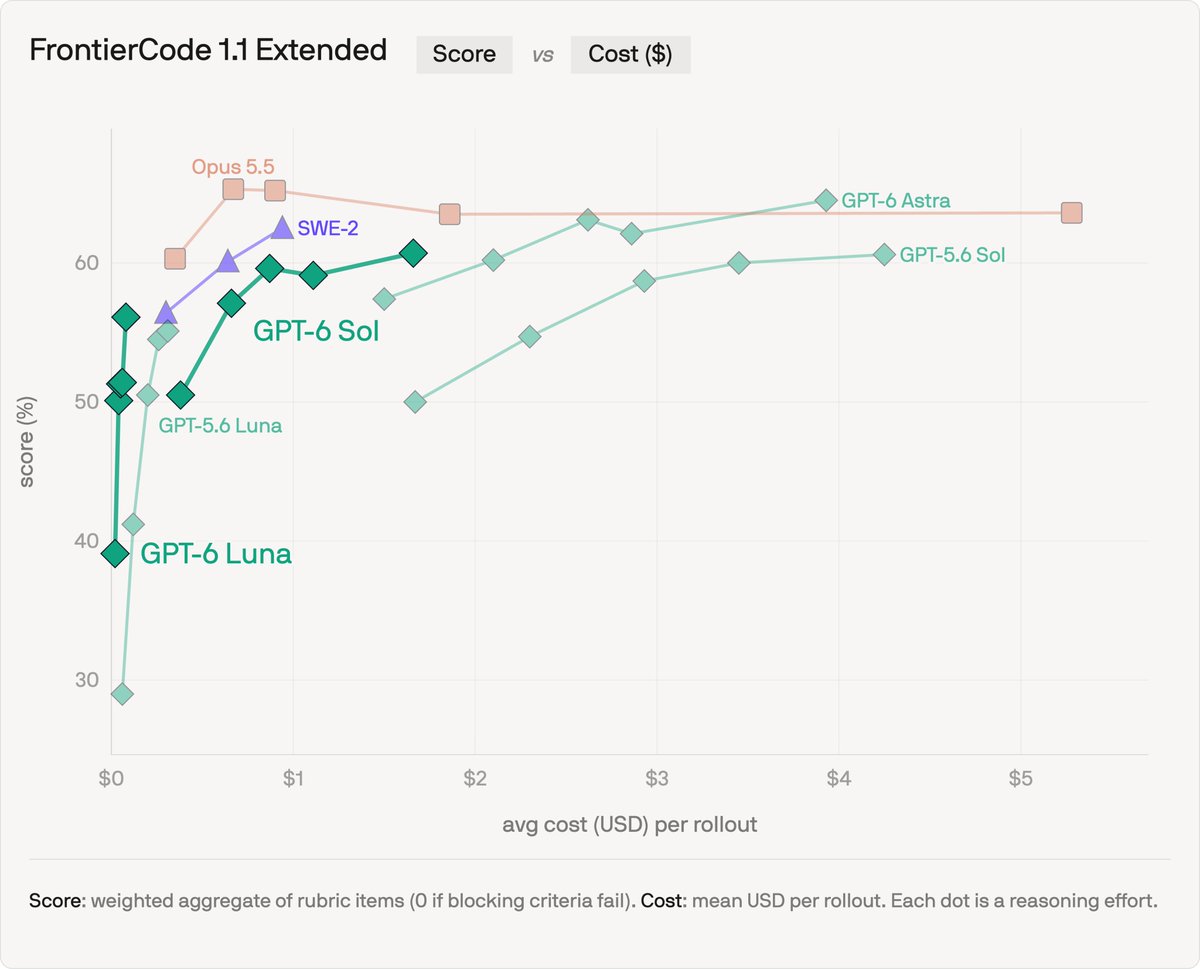
On FrontierCode 1.1, GPT-6 Sol matches GPT-5.6 Sol’s score at 61% lower cost per task. GPT-6 Luna scores above GPT-5.6 Luna at about a quarter of the cost. At under $0.10 per task, it is the cheapest model on the leaderboard. https://t.co/Mct0ZGxMO2
In our evaluations, we see that GPT-6 Sol reads about 17% less context than GPT-5.6 Sol to reach the same score, and rarely leaves a repo with failing tests after its last edit. GPT-6 Luna’s biggest gains are at low and medium reasoning effort, where it writes real regression tests instead of mock-based ones.
Read more: https://t.co/2pz6g4Agux
GPT-6 Sol and GPT-6 Luna are available in the API and rolling out in Codex and ChatGPT Work for Plus, Pro, Business, and Enterprise users.
https://t.co/fv2OS3jEI3
GPT-6 Sol and GPT-6 Luna build on Astra’s alignment advances, showing improvements over the GPT-5.6 Sol and GPT-5.6 Luna models in our alignment evaluations.
https://t.co/zdJfhce2O0
GPT-6 Sol and Luna just landed in Astra’s orbit.
Both launch today with API prices 50% lower than GPT-5.6.
Build with Sol. Scale with Luna. To production and beyond. https://t.co/ZCEFp4JdjV
On FrontierCode 1.1, our benchmark for real-world engineering tasks that grades mergeability and quality, Opus 5.5 scores 65.3% on Extended — taking the leading spot from Fable 5 at a fraction of the cost.
Read more: https://t.co/ELoIAbeica
Claude Opus 5.5 is now available in Devin.
On FrontierCode 1.1, Opus 5.5 takes the #1 sport from Fable 5 at a fraction of the cost. https://t.co/QUhqpGjO9X
🚀 @AnthropicAI's Claude Opus 5.5 is now generally available in GitHub Copilot.
Our early testing shows it stands out in efficiency, delivering task resolution comparable to Claude Opus 5 while using significantly fewer steps and tokens, with fast error recovery on multistep tasks.
Try it out for agentic coding, long-running agentic tasks, and knowledge work. Find it in the GitHub Copilot app, CLI, and @code.
https://t.co/tt9Pf4wAmv
Claude Opus 5.5 is now available in Cursor!
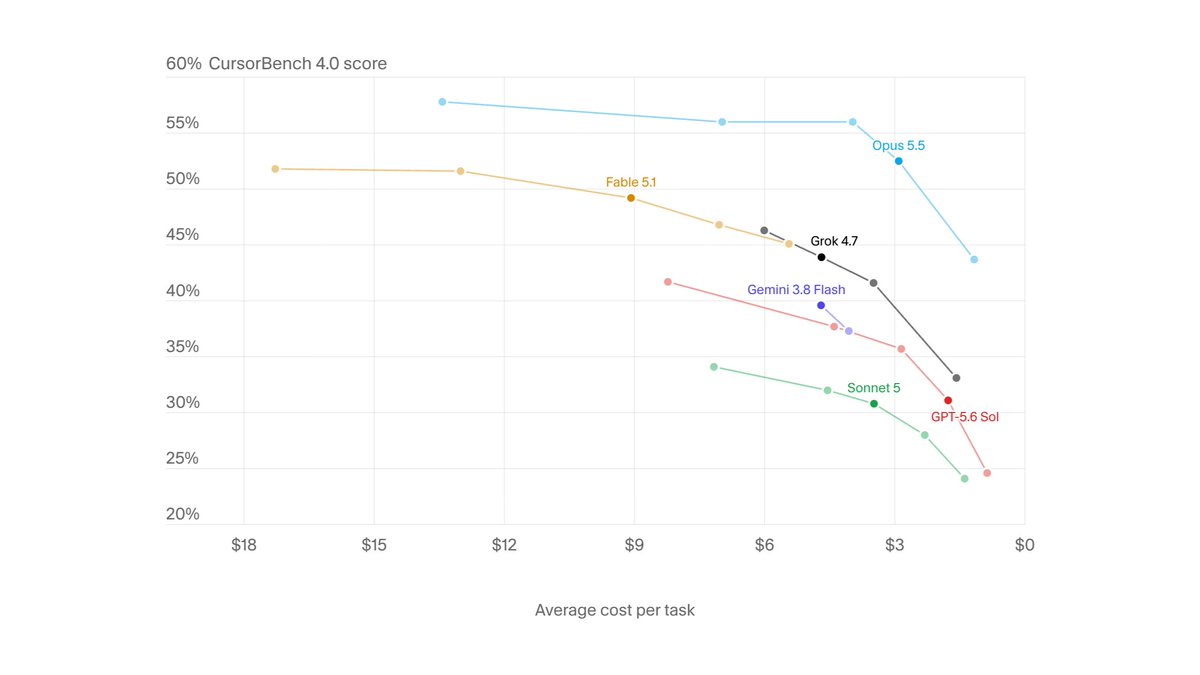
It's the new top model on CursorBench at 57.8% (Max) and costs 40% less per task than Opus 5. https://t.co/TMeNqjClCo
The fastest PDF-to-Markdown parser just got faster. ⚡️
With LiteParse v2.14.6, text-based PDFs parse about 25% faster.
Across realistic documents, LiteParse processed pages at 2.8ms/page and 1.5× faster than the next-fastest local parser.
LiteParse is open source and runs locally in Python, Node.js, Rust, or directly in the browser.
Grab v2.14.6 → https://t.co/UJy6KQ1Dyi
Bench Docs → https://t.co/rVY3Cxyj8H